In a clustered environment, each node in a cluster must share its result caches and intelligent cubes with the other nodes, so all clustered machines have the latest cache information. For example, for a project, result caches on each node that has loaded the project are shared among other nodes in the cluster that have also loaded the project. But how is this information synchronized across all nodes?
To understand the cube and cache synchronization workflow, you must first understand the files used by an intelligent cube and result cache.
There are four files that interact with an intelligence cube and cache:
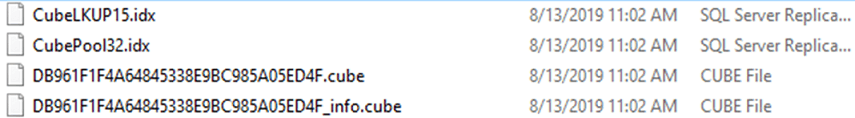
These files are stored in two locations:
Once the cube is published, these four files are loaded in-memory on the Intelligence Server. Based on performance concerns, the Intelligence Server will also save other remote cluster node's cube lookup indexes in-memory.
Once the cube is published, the Intelligence Server where the cube was published will back up the cube files on a disk. This behavior is controlled by the "Backup frequency (Minutes)" setting in the Server Configuration Editor.
For more information on the Backup frequency (Minutes) setting, see Configuring Result Cache Settings.
The following workflow details how a cube becomes synchronized after it is republished. In this example, we are using a two-node cluster. The cube is published in node A.
The following workflow details how cubes get synchronized again after the Intelligence Server rejoins the cluster. This example is using a two-node cluster.
Say cube 1 is published on node A. If node A's server goes down, cube 1 is republished on node B and a new cube, cube 2, is published on node B.
On node B's server, before server A rejoins the cluster, there are now duplicate cube instances for cube 1 listed in the cube monitor. However, only the latest cube 1 instance will be hit. Once server A has completely rejoined the cluster, the duplicate cube instance of cube 1 will be removed from the server memory.
After node A has rejoined the cluster, the old cube instance of cube 1 will be removed from both the server memory and disk of node A. Then, the newly published cube instance from cube 1 and cube 2 will be loaded into node A's server memory. Now, both servers have the same cube instance loaded.
Note: Only the cache list created by the current Intelligence Server will appear in the cache monitor. As such, there will be no duplicate cache observed in this scenario.
For more information, see Synchronizing Cached Information Across Nodes in a Cluster.
